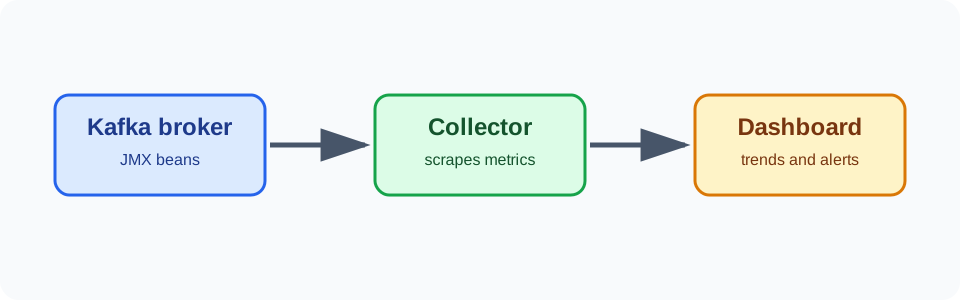
The first JMX screen I opened contained more metrics than I knew what to do with. Every number looked important. After a while I started grouping them by the question I was trying to answer instead of building a dashboard from every available bean.
Start with traffic#
For a broker, BytesInPerSec and BytesOutPerSec tell me how much data is moving. I compare the rate with the baseline for that environment and with disk and network capacity.
An increasing traffic rate is not a problem by itself. It becomes interesting when it appears with rising request time, disk saturation, or growing consumer lag.
Then look at latency#
Kafka exposes request timing that can be divided into queue time, local processing time, and response or total time. The distinction matters:
- Queue time suggests the broker is waiting for capacity.
- Local time suggests work inside the broker is taking longer.
- Network time suggests a client or network path may be involved.
I avoid reacting to one spike. I look for a sustained change and compare it with deployment, workload, and partition events.
Consumer lag is a symptom#
Lag means that a consumer is behind the end of the partition. It does not tell me why. I ask:
- Did the producer rate increase?
- Did the consumer slow down?
- Did a rebalance interrupt processing?
- Is the consumer waiting on a downstream database or API?
- Are partitions distributed evenly across consumers?
The useful chart is usually lag together with records consumed and processing latency. A lag number without throughput context is easy to misread.
Replication health#
Under-replicated partitions are a cluster-health signal. I correlate them with broker restarts, network events, disk errors, and controller changes. If the count remains non-zero, I treat it as an active problem rather than an interesting graph.
Offline partitions are more severe: clients cannot read or write those partitions normally. The response should be operational, not merely a dashboard annotation.
JVM and operating system signals#
Kafka’s Java metrics should be read alongside the host:
- heap use and garbage collection;
- CPU saturation;
- disk latency and free space;
- network throughput;
- open file descriptors.
For example, high heap use with long garbage-collection pauses and rising request latency points in a different direction than high heap use with short collections and stable latency.
A small interpretation routine#
When something looks wrong, I now use this order:
traffic -> latency -> consumer lag -> replication -> JVM -> hostIt is not a law. It is a way to avoid jumping from one alarming gauge to an unrelated change. JMX gives the evidence; the timeline and the workload provide the interpretation.
The most useful dashboard is the one that helps me explain what changed, when it changed, and which next check will confirm or reject the first theory.
Illustrative comparison:
Before deployment: lag=120, consume-rate=1,020 records/sec
After deployment:  lag=40,000, consume-rate=115 records/sec
Broker bytes in:   unchanged
That pattern would move my attention away from the producer and toward the consumer deployment or its downstream dependency. The unchanged broker input says the cluster may simply be delivering the same workload to a slower consumer.